The debate on digital privacy consistently revolves around the argument "I have nothing to hide"[1]. This argument is built on the fundamental assumption that privacy is strictly identical to secrecy: if an individual does not engage in illicit or embarrassing conduct, data collection poses no meaningful threat[2]. However, recent events—from the Cambridge Analytica psychographic targeting scandal[3] to empirical studies on how biased AI assistants covertly shift users' social attitudes[4]—have demonstrated that mass data collection combined with modern predictive modeling can shape reality through the manipulation of human beliefs.
Privacy as Secrecy
The traditional view of privacy is often framed as "secrecy"—keeping personal information hidden. But in the age of predictive analytics, data is not just collected; it is inferred. You can keep a secret, but algorithms might guess it anyway.
Lack of Transparency
Predictive models operate in a black box. Even if you have "nothing to hide," you often have no visibility into how your data is being used, what conclusions are drawn, or how those conclusions impact your opportunities.
Lack of Knowledge
Innocent data points can be combined to generate highly sensitive knowledge about your life. The "nothing to hide" argument fails because users do not realize what information they are actually revealing.
From Purchases to Revealing Secrets
Artificial intelligence has developed an extraordinary capacity for extracting sensitive inferences from otherwise mundane records. A classic example is the case of Target, where predictive analysts identified a customer's pregnancy prior to her family finding out simply through the combinatorial analysis of twenty-five innocuous shopping items, such as unscented lotion, magnesium, and zinc supplements[5]. Today, algorithmic capabilities have expanded exponentially: multimodal and generative AI models can parse longitudinal electronic health records to calculate the statistical probability of over a thousand diseases up to two decades in advance[6].
1. Raw Loss Terrain
Non-convex, chaotic data surface2. Pre-Processed Embedding
Normalized latent manifold3. Live Gradient Descent
Optimizing parameter vector $\theta$4. Decision Hyperplane
Partitioning multi-class spaceFurthermore, pervasive sensor tracking turns everyday devices into ubiquitous surveillance instruments[7]. By mining large sequential datasets with prescriptive analytics[8] and utilizing modern Vision-Language Models (VLMs), systems can deduce sensitive socioeconomic profiles, personality metrics, and demographic traits through the simple analysis of casual photographs[9].
Everyday phrasing carries statistical dialect markers. Language models analyze conversational cadence to unmask hidden demographics without direct disclosure:
Biases and "Smart" Discrimination
Because predictive algorithms optimize on historical data, they inevitably codify and amplify systemic human discrimination[10]. Instead of eliminating human partiality, algorithms frequently automate prejudice behind a facade of mathematical objectivity:
- Judicial Recidivism (COMPAS): The commercial COMPAS scoring system exhibited severe racial disparity, falsely classifying Black defendants as high-risk recidivists at nearly double the rate of white defendants, while systematically underestimating the risk of white re-offenders[11], [12].
- Automated Hiring: Amazon's proprietary resume-filtering algorithm systematically penalized CVs that included terms like "women's" (e.g., "women's chess club") after learning from a decade of male-dominated tech hiring records[13].
- Healthcare Resource Allocation: Commercial risk-scoring algorithms assigned lower health-need scores to minority patients with identical illness severity because the algorithm used prior healthcare spending as a proxy for healthcare need[14].
Empirical false-positive rates (defendants predicted to re-offend who did not re-offend over a 2-year window):
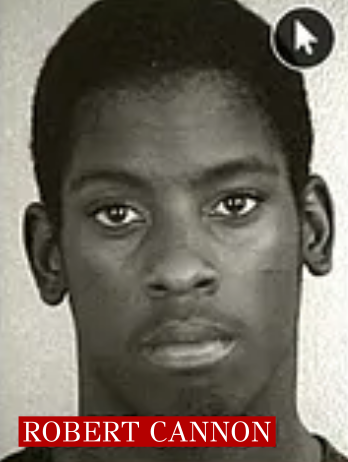
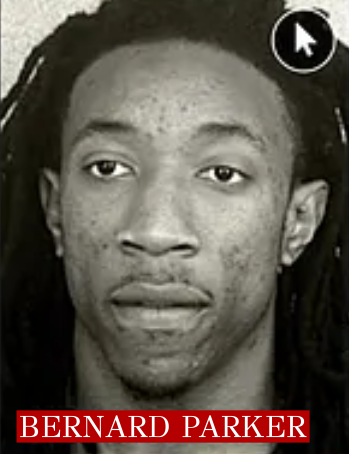
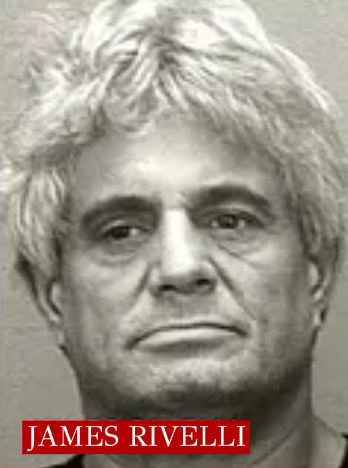
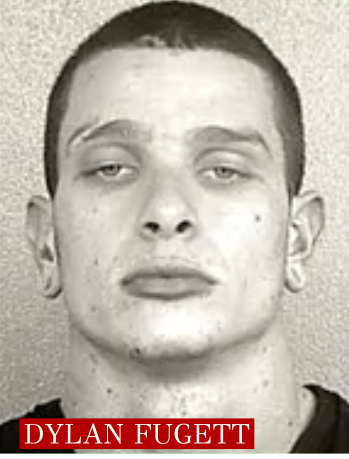
Real defendant cases analyzed by ProPublica illustrating algorithmic bias. Despite identical or lower prior charges, minority defendants received dramatically inflated risk ratings:
New Threats and "Invisible" Attacks
Model inference attacks exploit the statistical outputs of trained neural networks to reconstruct underlying training samples or infer attributes that the user explicitly chose not to disclose[15]. Commercial facial search platforms like PimEyes ingest billions of unindexed images across the web, allowing any third party to reverse-search a stranger's face and unmask their identity within seconds[16]. Simultaneously, visual geolocation tools like GeoSpy extract geographic coordinates from background lighting, building facades, and vegetation patterns without requiring EXIF GPS data[17].
When these models are mounted onto smart consumer eyewear—such as Meta's Ray-Ban smart glasses—the boundary between cyberspace and physical space collapses entirely[18]. Passersby involuntarily broadcast real-time biometric and location data without notice or consent, converting public life into an unconsented surveillance arena.
Technological and Legal Shields (and their loopholes)
Technological mechanisms offer partial mitigation. Differential Privacy injects calibrated statistical noise (e.g., Laplace or Gaussian noise) into query outputs, guaranteeing mathematical indistinguishability so that the presence or absence of any individual in the dataset cannot be verified with confidence[19], [20]. Similarly, Fully Homomorphic Encryption (FHE) permits servers to execute mathematical operations on ciphertexts directly, allowing cloud models to compute inference predictions without ever decrypting user data into plaintext[21].
The Fragility of Inferential Decision Boundaries
Beyond cryptographic defenses and mathematical indistinguishability, examining the geometric topology of high-dimensional machine learning representations reveals profound structural fragilities. Deep neural networks, rather than operating with robust non-linear common sense, exhibit extensive linearity across high-dimensional feature spaces[26]. As pioneered by Goodfellow et al. via the Fast Gradient Sign Method (FGSM), injecting an infinitesimal, adversarially calibrated perturbation vector ($\epsilon$) along the gradient of the loss function suffices to propel an input point straight across the model's decision boundary hyperplane. While the resulting input remains entirely indistinguishable from the original sample to the human eye, the automated inference engine undergoes a total categorical inversion—causing a clean input previously recognized as a Panda with 57.7% confidence to be misclassified with near-total certainty as a Gibbon (99.3% confidence). In adversarial surveillance and predictive profiling contexts, this vulnerability cuts both ways: algorithmic inferences can be subtly weaponized or manipulated without leaving any perceptible trace in physical reality.
On the regulatory front, the European Union's General Data Protection Regulation (GDPR) establishes the right not to be subjected to decisions based solely on automated processing (Article 22)[22], and severely restricts processing of special categories of personal data (Article 9), when utilizing AI as a legal basis (that said before Omnibus) [23]. In parallel, the EU AI Act explicitly prohibits manipulative cognitive behavioral systems and social scoring applications[22].
However, critical loopholes remain unresolved:
- Derived vs. Provided Data: The GDPR regulates collected personal data far more strictly than statistically inferred probabilistic data[23].
- Rubber-Stamp Human Oversight: The prohibition on purely automated decisions can be circumvented through the formal placement of a human supervisor who simply validates machine recommendations without meaningful independent scrutiny[23].
Conclusion: The Imperative of Algorithmic Literacy
The defensive argument "I have nothing to hide" is an obsolete relic of an analog era. In an interconnected AI ecosystem, privacy is not secrecy; it is freedom from unauthorized statistical inference[1]. Innocent, uncoordinated digital footprints are sufficient to deduce our deepest medical, political, and personal vulnerabilities[18].
To defend individual agency, cultivating algorithmic literacy is an urgent societal necessity[24]. Citizens and engineers alike must understand how machine learning models harvest innocuous breadcrumbs to shape behavioral autonomy and ensure technological architectures serve human dignity rather than surveillance capitalism[25].
- [1] I. N. Cofone, “Nothing to hide, but something to lose,” University of Toronto Law Journal, vol. 70, no. 1, pp. 64–90, Nov. 2019, doi: 10.3138/utlj.2018-0118. ↩
- [2] Στέφανος Γκρίτζαλης, Σωκράτης Κ. Κάτσικας, Κωνσταντίνος Λαμπρινουδάκης, and Λίλιαν Μήτρου, Προστασία της ιδιωτικότητας και τεχνολογίες πληροφορικής και επικοινωνιών: Τεχνικά και νομικά θέματα. Παπασωτηρίου, 2010. ↩
- [3] R. Chan, “The Cambridge Analytica whistleblower explains how the firm used Facebook data to sway elections,” Business Insider, Oct. 2019. ↩
- [4] S. Williams-Ceci, M. Jakesch, A. Bhat, K. Kadoma, L. Zalmanson, and M. Naaman, “Biased AI writing assistants shift users’ attitudes on societal issues,” Science Advances, vol. 12, no. 11, p. eadw5578, Mar. 2026, doi: 10.1126/sciadv.adw5578. ↩
- [5] C. Duhigg, “How companies learn your secrets,” The New York Times, Feb. 2012. ↩
- [6] Y. Wu, “AI uses medical records to accurately predict onset of disease 20 years into the future,” Nature, vol. 647, no. 8088, pp. 44–45, Nov. 2025, doi: 10.1038/d41586-025-02971-3. ↩
- [7] “Digital surveillance turns everyday devices into evidence,” IEEE Spectrum, Apr. 2026. ↩
- [8] D. Frazzetto, T. D. Nielsen, T. B. Pedersen, and L. Šikšnys, “Prescriptive analytics: A survey of emerging trends and technologies,” The VLDB Journal, vol. 28, no. 4, pp. 575–595, Aug. 2019. ↩
- [9] F. Liu et al., “The eye of Sherlock Holmes: Uncovering user private attribute profiling via vision-language model agentic framework,” in Proceedings of the 33rd ACM International Conference on Multimedia (MM ’25), Oct. 2025, pp. 4875–4883. doi: 10.1145/3746027.3755643. ↩
- [10] J. Johansen, T. Pedersen, and C. Johansen, “Studying the transfer of biases from programmers to programs,” AI & Society, vol. 38, no. 4, pp. 1659–1683, Aug. 2023, doi: 10.1007/s00146-021-01328-4. ↩
- [11] S. Corbett-Davies, E. Pierson, A. Feller, and S. Goel, “A computer program used for bail and sentencing decisions was labeled biased against blacks. It’s actually not that clear,” The Washington Post, Oct. 2016. ↩
- [12] C. Engels, L. Linhardt, and M. Schubert, “Code is law: How COMPAS affects the way the judiciary handles the risk of recidivism,” Artificial Intelligence and Law, vol. 33, no. 2, pp. 383–404, Jun. 2025, doi: 10.1007/s10506-024-09389-8. ↩
- [13] J. Dastin, “Insight - Amazon scraps secret AI recruiting tool that showed bias against women,” Reuters, Oct. 2018. ↩
- [14] J. L. Cross, M. A. Choma, and J. A. Onofrey, “Bias in medical AI: Implications for clinical decision-making,” PLOS Digital Health, vol. 3, no. 11, p. e0000651, Nov. 2024, doi: 10.1371/journal.pdig.0000651. ↩
- [15] R. Staab, M. Vero, M. Balunović, and M. Vechev, “Beyond memorization: Violating privacy via inference with large language models,” arXiv, 2024. doi: 10.48550/arXiv.2310.07298. ↩
- [16] “PimEyes: Face recognition search engine and reverse image search,” 2026. [Online]. Available: https://pimeyes.com ↩
- [17] J. Cox, “The powerful AI tool that cops (or stalkers) can use to geolocate photos in seconds,” 404 Media, Apr. 2026. ↩
- [18] “Meta AI glasses: Ray-Ban Meta smart glasses,” Meta Store, 2026. ↩
- [19] C. Dwork, “Differential privacy: A survey of results,” in Theory and Applications of Models of Computation, vol. 4978, Springer, 2008, pp. 1–19. doi: 10.1007/978-3-540-79228-4_1. ↩
- [20] F. Aguilera-Martínez and F. Berzal, “Differential privacy in machine learning: A survey from symbolic AI to LLMs,” arXiv, 2026. doi: 10.48550/arXiv.2506.11687. ↩
- [21] O. Karanikolas, “Privacy and data protection risks in large language models,” PhD thesis, University of Piraeus, 2024. ↩
- [22] C. Sarra, “Artificial intelligence in decision-making: A test of consistency between the ‘EU AI Act’ and the ‘General Data Protection Regulation’,” AJL, vol. 11, no. 1, pp. 45–62, Jan. 2025. ↩
- [23] M. Brkan, “Do algorithms rule the world? Algorithmic decision-making and data protection in the framework of the GDPR and beyond,” International Journal of Law and Information Technology, vol. 27, no. 2, pp. 91–121, Jun. 2019. ↩
- [24] A. Cox, “Algorithmic literacy, AI literacy and responsible generative AI literacy,” Journal of Web Librarianship, vol. 18, no. 3, pp. 93–110, Jul. 2024. ↩
- [25] H. Zhou, “Intelligent personalized content recommendations based on neural networks,” International Journal of Intelligent Networks, vol. 4, pp. 231–239, 2023. ↩
- [26] I. J. Goodfellow, J. Shlens, and C. Szegedy, “Explaining and harnessing adversarial examples,” in International Conference on Learning Representations (ICLR), 2015. doi: 10.48550/arXiv.1412.6572. ↩